Introducing /answers: web research in one API call
Backed byYCombinator

See what is on a site.
Choose what to scrape.

Discover URLs across a domain, with page titles and descriptions when available. Build the map before you collect the content.

stripe.com

Map domains

Discovered pages

Example map

  • Payments

    stripe.com/payments

  • Billing

    stripe.com/billing

  • Pricing

    stripe.com/pricing

  • Documentation

    docs.stripe.com

Teams build with Context.dev

  • Mintlify
  • daily.dev
  • Daydream
  • Super.com
Discover page URLs
Start from a domain and get a list of pages to use in your content workflow.
Scope the discovery
Include subdomains and set a maximum number of links for your request.
Use available metadata
Read titles and descriptions when available. Newly discovered URLs can arrive before enrichment.

Map first.
Then collect.

Use mapUrls to discover pages. Pass the URLs you want into Scrape or Batches when you are ready to retrieve their content.

npm install context.dev
TypeScriptmap.ts
import ContextDev from 'context.dev';

const client = new ContextDev({ apiKey: 'YOUR_API_KEY' });

const { urls } = await client.web.mapUrls({
  domain: 'stripe.com',
  includeSubdomains: true,
  maxLinks: 100,
});

for (const page of urls) {
  console.log(page.url, page.title, page.description);
}

Turn a site map
into a useful dataset.

Discover the pages, then build the content workflow that your product needs.

Scrape Anything

Read websites and PDFs. Get clean Markdown, HTML, structured JSON, images, and screenshots in the formats your product needs.

context.devWebpages & PDFs
# Web data API for AI agents

Web scraping, data, and
search infrastructure
for AI products.

Screenshot
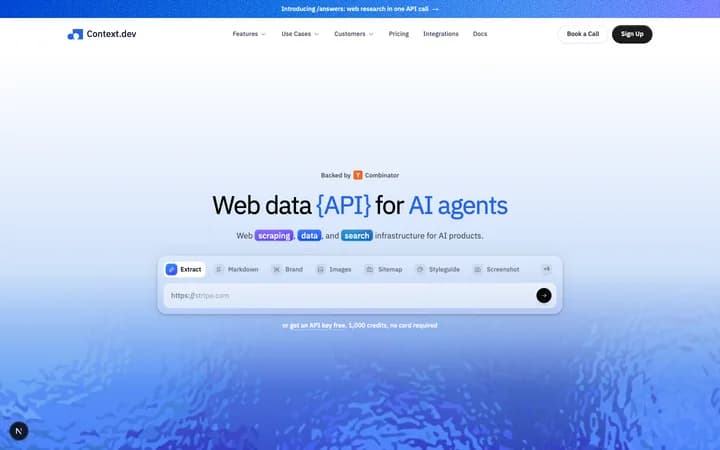
Context.dev homepage captured as a screenshot

Images

Blue glass artwork from the pageContext.dev logo from the page
Multiple formats, one requestExample outputs

Run batches at scale

Scrape thousands of URLs in one job. Process large URL lists or crawl entire sites, then collect results when the batch completes.

Example batch · Markdown

Running

25,000 URLs

78.7%

19,680 complete

5,320 remaining

Browse results →

Paginated dataset

Large URL lists · Full-site crawls

A few things
to know.

More details in the API documentation.

Does Map return the content of every page?

Map returns discovered URLs and available metadata. Use Scrape for page content, or submit the discovered URLs to a batch for larger collection jobs.

Can I include subdomains?

Yes. Set includeSubdomains for the domain discovery request.

Can I limit the number of URLs?

Yes. Use maxLinks to bound the number of discovered links returned for your request.

Why might a title or description be missing?

URLs without stored enrichment can be returned immediately and queued for background HTML scraping. Later requests may include the additional metadata.

Start with your next request.

One API key for scraping, research, brand data, batches, and monitoring.