
At Context.dev, we do everything possible to make scraping and processing pages as fast as physically possible. While fetching a page will always have some latency, anything else that happens between us receiving a request and returning a page is overhead that can be optimized.
Once the HTML arrives, we still need to figure out which parts are useful, remove anything unwanted, and serialize the result. We've been using Cheerio since the beginning, and we love its jQuery-like API and simplicity, but performance became a bottleneck at our scale.
The solution was to port Cheerio to Rust. Previously, that project likely wouldn't have been worth it for us. With LLMs, it became an exercise that took under a day and around $1,000 in LLM spend.
The result is Rusteerio, built as a drop-in replacement for Cheerio, targeting Cheerio 1.2.0's behavior. Parsing, selectors, mutations, and serialization run in Rust; the familiar JavaScript API stays completely unchanged.
The hard part was compatibility. A faster parser that subtly changes the HTML would just move the work into debugging our scrapers. Rusteerio passes all 777 upstream Cheerio tests without changing any original assertions or fixtures, and with no added skips.
We also compared a full processing pipeline on 5,000 Common Crawl pages, and every result matched the original Cheerio version. Our benchmark parses each page, extracts metadata and links, walks the DOM, removes scripts and styles, and returns text and serialized HTML. While Cheerio took 22.5 seconds, Rusteerio took 10.2 seconds, which is a 2.22× speedup.
The 5,000-page run used the same library versions on Linux with an AMD Ryzen 9 9950X, 8 vCPUs, 16 GB RAM and Node 24.18.1. Both benchmarks exclude network fetching. Pipeline and reproduction instructions.
View benchmark results as a table
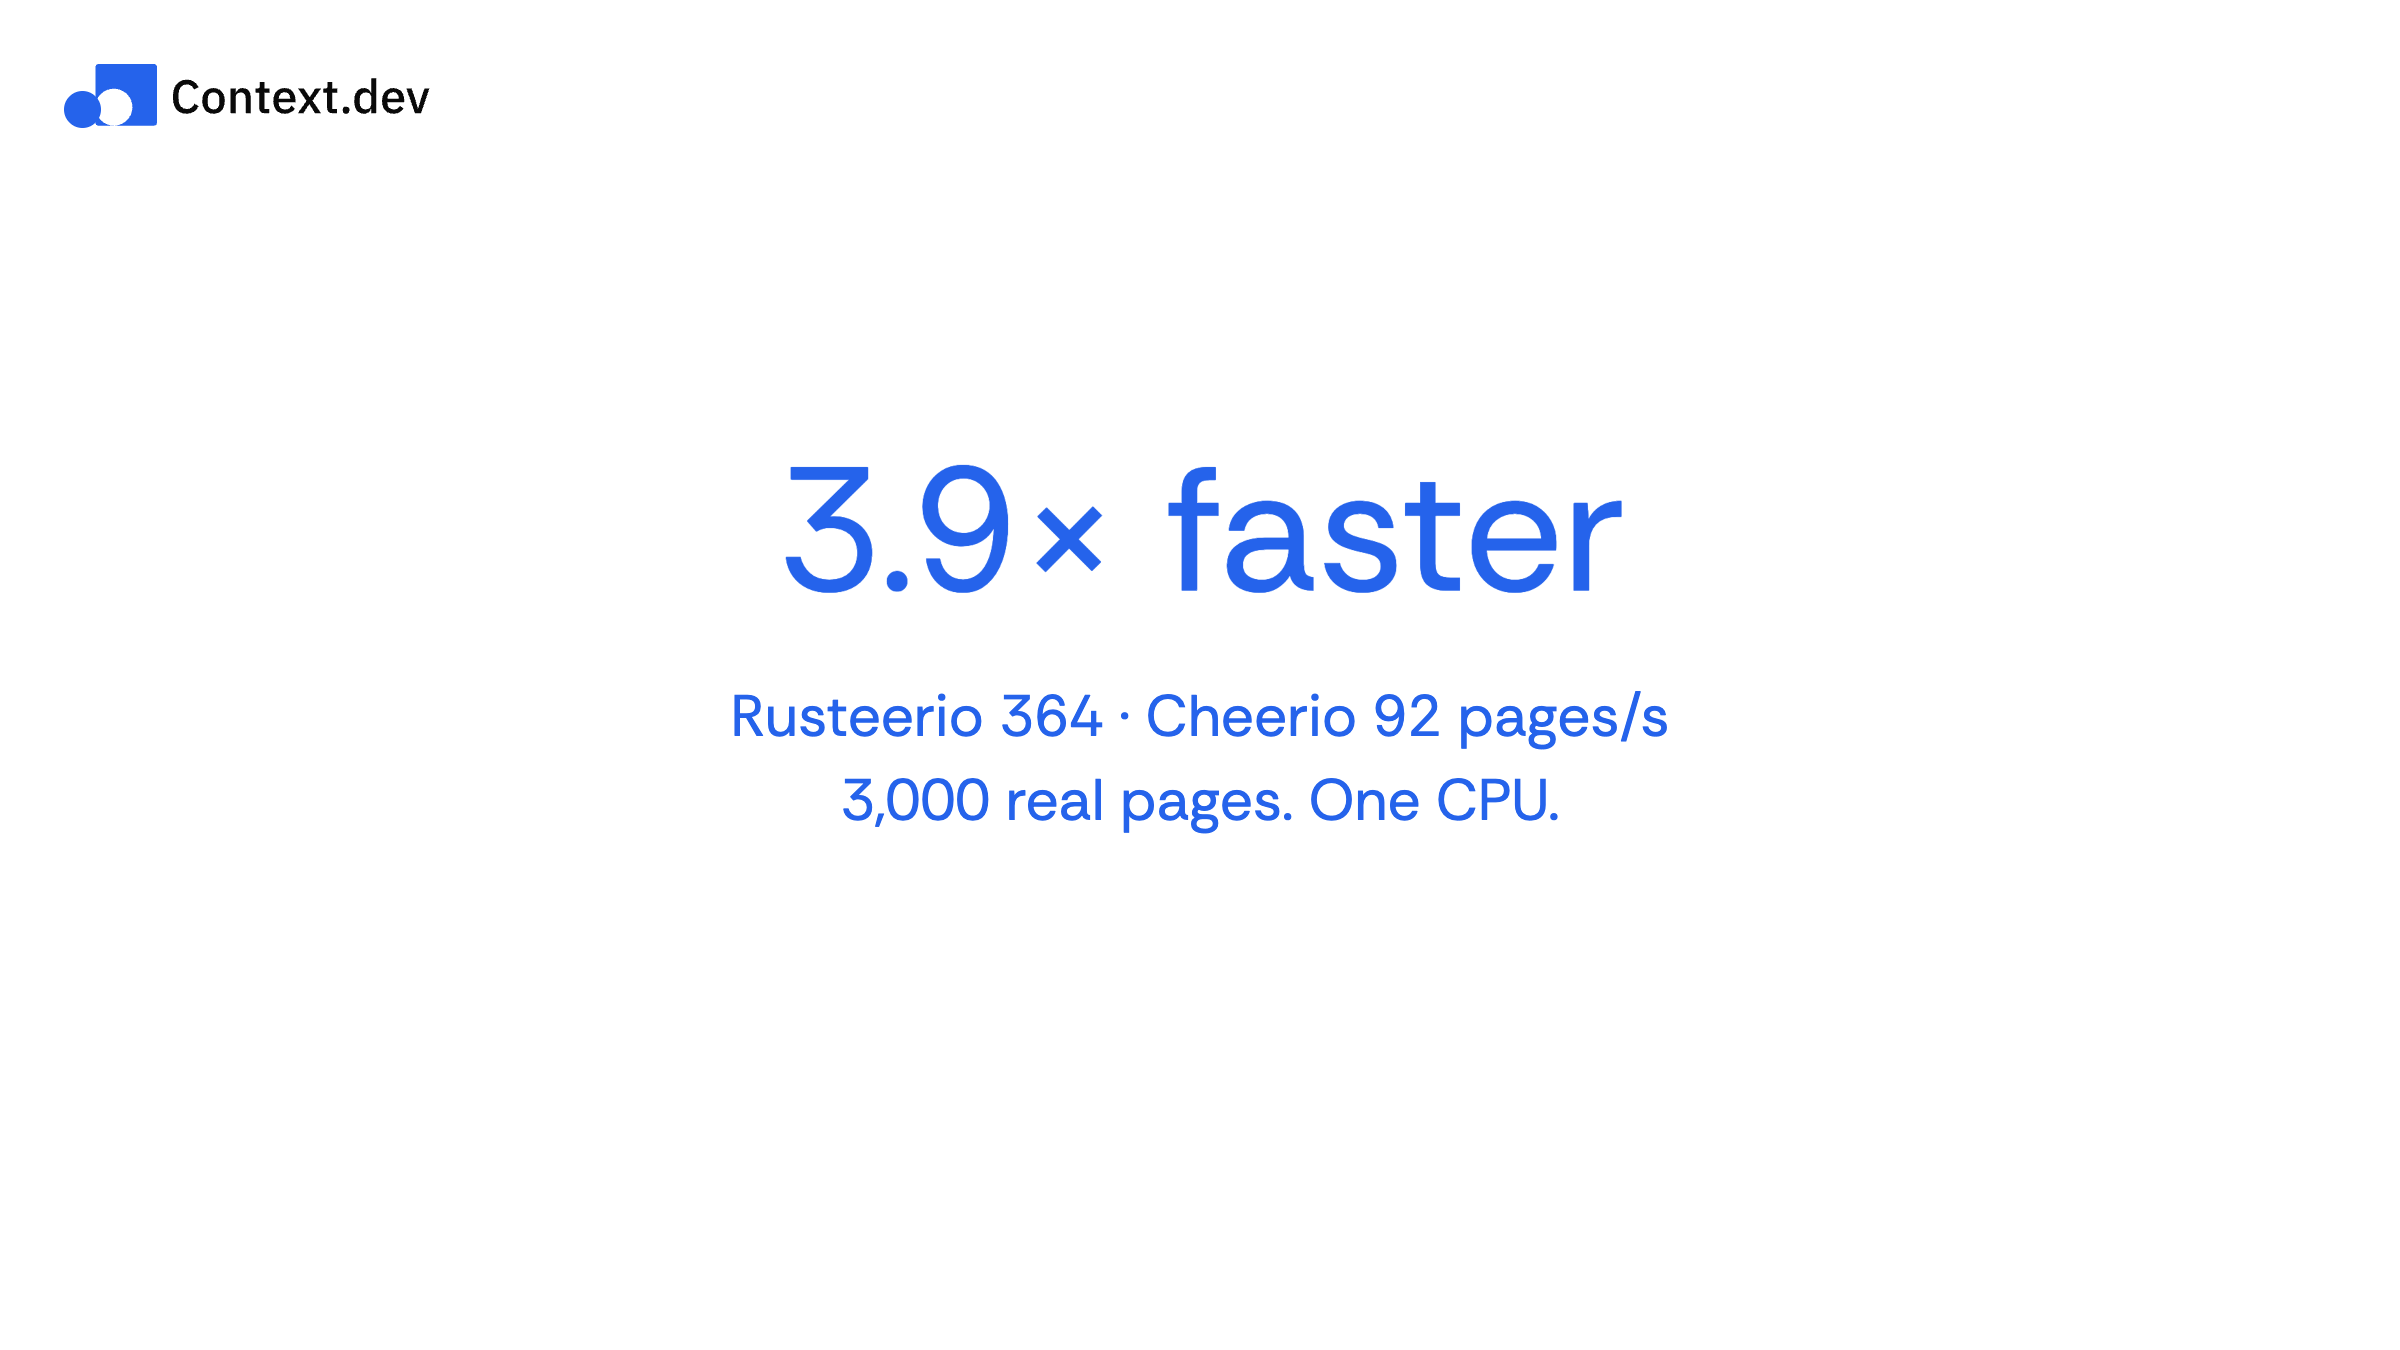
Parse + extract: 3,000 pages, one CPU
| Library | Pages per second |
|---|---|
| Cheerio | 92 |
| Rusteerio | 364 |
Full pipeline: 5,000 pages
| Library | Total time |
|---|---|
| Cheerio | 22.5 seconds |
| Rusteerio | 10.2 seconds |
Open source, ready to try
We're open sourcing Rusteerio, now at 2.0.0, under the MIT license, including the compatibility suite and benchmarks. Install it, swap the import, and run it against your own pages:
npm install rusteerioimport * as cheerio from 'rusteerio';
const $ = cheerio.load('<h1>Hello, Rusteerio</h1>');
console.log($('h1').text());It ships prebuilt native binaries for macOS, Linux, and Windows and requires Node.js 20.19 or later.